Posts By :

Nadeem Shaikh

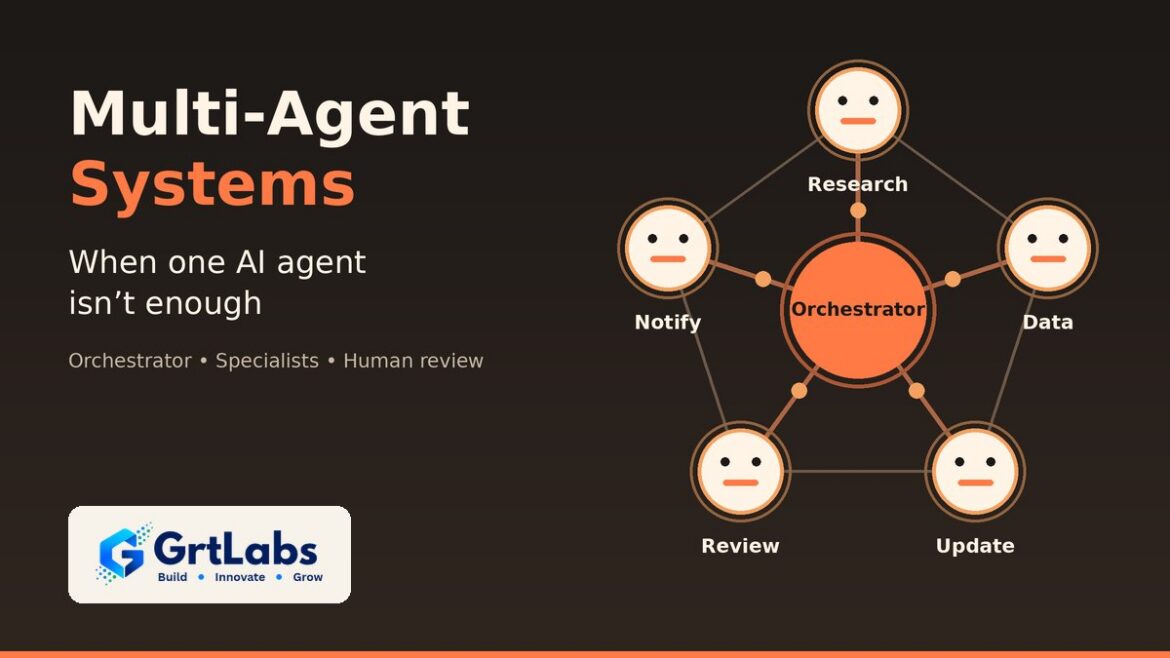
Charcoal and coral GrtLabs graphic of an orchestrator AI agent passing tasks to Research, Data, Update, Review and Notify agents, illustrating multi-agent systems.
Multi-Agent Systems: When One AI Agent Isn’t Enough
Multi-Agent Systems: When One AI Agent Isn’t Enough 1024 576 Nadeem Shaikh

A multi-agent system is a setup where several AI agents, each with its own job, tools and permissions, work together on one task. Usually an orchestrator agent breaks the work into steps and hands each step to a specialist agent, such as one that researches, one that updates records and one that checks the result. It makes sense when a single agent has too many tools, too many rules or too much context to handle reliably. For simple, well-defined jobs, one agent is still the better choice.

If you have already tried a single AI agent, you may have seen it work well on a narrow task and then struggle as you add more systems, more instructions and more exceptions. Splitting the work across several focused agents is one way to fix that. It also adds cost and complexity, so it is worth knowing when it pays off and how to build it so you stay in control.

What is a multi-agent system?

An AI agent is software that is given a goal, a set of tools it may use and rules for when to stop and ask a person. It plans the steps, calls the tools and finishes the work. If that idea is new, start with our plain-English guide to what agentic AI is.

A multi-agent system puts several of these agents together. Each agent has a narrow role, a short set of instructions and access to only the tools it needs. The agents pass work to each other through defined handoffs: a task, the context needed to do it, and the result that comes back.

Think of it like a small team rather than one very busy employee. A coordinator assigns tasks, specialists do their part, and someone checks the work before it goes out. The difference is that each team member is a piece of software you can test, log and limit.

When one AI agent isn’t enough

A single agent is easier to build, cheaper to run and simpler to debug. Start there. Consider more than one agent when you see signs like these:

  • Too many tools. As an agent gets access to more and more tools, it is more likely to pick the wrong one. Smaller agents with a handful of tools each tend to choose better.
  • Instructions that conflict. One prompt that tries to cover sales rules, finance rules and support tone at once becomes long and fragile. Separate agents can each follow one clear set of rules.
  • Too much context. Long documents, account history and tool results can crowd out what matters. A specialist agent only sees the context for its step.
  • Different permission levels. A research step may only need read access, while an update step needs write access to your CRM or ERP. Splitting agents lets you give each one the least access it needs.
  • Work that can run in parallel. Checking several systems or documents at the same time can be faster when separate agents handle each one.
  • A need for independent review. A separate checker agent, with its own instructions, can catch mistakes the first agent missed before a person reviews the result.

If none of these apply, a single well-designed agent, or even a plain workflow automation, is usually the right answer.

Common multi-agent patterns

Most business multi-agent systems use one of a few patterns, or a mix of them:

  • Orchestrator and workers. A coordinating agent reads the request, splits it into tasks, sends each task to a specialist agent and assembles the results. This is the most common pattern for business workflows.
  • Router. A front agent decides what kind of request has come in and sends it to the right specialist, for example billing, technical support or sales.
  • Sequential pipeline. Agents work in a fixed order, like an assembly line: extract the data, check it against your rules, then draft the update. Each agent’s output is the next agent’s input.
  • Maker and checker. One agent produces a draft and another reviews it against a checklist, sending it back if it falls short. A person still approves anything sensitive.
  • Parallel research. Several agents look at different sources at the same time and a final agent combines what they found.

Open-source frameworks such as LangGraph, Microsoft AutoGen and CrewAI, and vendor toolkits such as the OpenAI Agents SDK, provide building blocks for these patterns. Standards are also emerging for how agents connect: the Model Context Protocol (MCP) for connecting agents to tools and data, and the Agent2Agent (A2A) protocol for agents talking to other agents. Our guide to building a custom MCP server covers the tool side in more depth. The framework matters less than the design: clear roles, clear handoffs and clear limits.

Business use cases for multi-agent systems

Multi-agent systems fit work that crosses several systems and needs a decision at each step. Examples include:

  • Support triage. One agent classifies the ticket, another gathers account and order context, and a third drafts a reply for a person to review.
  • Sales operations. A research agent looks up a lead, an enrichment agent fills in missing fields, and an update agent writes the result to the CRM after checks pass.
  • Order and inventory exceptions. Agents check order status, stock levels and shipping data in separate systems, then flag the exceptions that need a human decision.
  • Document-heavy back office. An extraction agent reads invoices or contracts, a validation agent checks them against your rules, and anything that does not match goes to a review queue.
  • Internal help desks. A router sends HR, IT and policy questions to agents that answer from the right approved documents and file requests when needed.

The trade-offs: cost, speed and debugging

More agents means more moving parts. Be honest about the costs before you build:

  • More model calls. Every handoff and review step is another call to a language model, which adds usage cost.
  • Slower responses. Steps that run one after another add up. Parallel work helps, but a multi-agent flow is rarely as fast as one call.
  • Errors can compound. If an early agent gets something wrong and passes it on, later agents may build on the mistake. Checks between steps matter.
  • Harder debugging. When the final result is wrong, you need to see which agent made which decision, with what input.
  • Agents can loop. Two agents can keep handing work back and forth. Set limits on steps, retries and time.

How to build a multi-agent system you can trust

The same principles that make a single agent safe matter even more when several agents work together:

  • Start with one workflow. Pick a well-defined process with a clear outcome, prove it on your own data, then expand.
  • Give each agent one job. Write down each agent’s goal, its tools, its permissions and when it must stop and ask a person.
  • Use least-privilege access. Read-only where possible, write access only where needed, and approval steps for sensitive actions such as payments, deletions or customer messages.
  • Define the handoffs. Agree on what each agent receives and returns, in a structured format, so the next step can check it.
  • Keep a human in the loop for decisions that carry real risk, and make escalation easy.
  • Log every step. Record which agent did what, with which inputs and tools, in a log the agents cannot change. Our guide to an AI agent audit trail explains how.
  • Test and monitor. Evaluate the system against real examples before launch, and keep monitoring quality, cost and errors afterwards.

For the policy side, including who approves what and how you roll agents out, see our guide to AI agent governance. For keeping AI systems reliable after launch, see LLMOps explained.

How GrtLabs can help

GrtLabs is a Houston AI lab that builds agentic AI for teams that need software that can plan, call tools and finish multi-step work. We design agents that connect to your APIs, databases, documents and workflows, with clear guardrails and human review where it matters. Our work is built for operations, support, sales ops and internal tools, not demos.

Every engagement follows the same path. In discovery we pick one well-defined workflow and agree on each agent’s goal, tools, permissions and escalation rules. We then build and test with your team in short iterations, deploy with human approval steps and logging so you can see every step the agents took, and hand off with documentation and training. Agents can run on AWS or Azure for models, retrieval and secure hosting.

The same Houston team also builds RAG knowledge systems, AI automation, custom web and app development, and GRTforms, our own online form builder with AI form creation.

Have a workflow that one agent can’t handle? Talk to our Houston team about your use case, or see our agentic AI services.

Frequently asked questions

What is a multi-agent system in AI?

A multi-agent system is a group of AI agents that each have their own role, tools and permissions and work together on one task. An orchestrator agent usually splits the work and hands each step to a specialist agent, then combines the results.

What is the difference between a single AI agent and a multi-agent system?

A single agent handles the whole task with one set of instructions and tools. A multi-agent system splits the task across several focused agents, which helps when one agent would need too many tools, rules or context, but it adds cost and complexity.

When should a business use a multi-agent system?

Use one when a workflow crosses several systems, needs different permission levels for different steps, benefits from an independent review step, or has grown too complex for one agent to handle reliably. For simple tasks, start with a single agent.

How do you keep multi-agent systems safe?

Give each agent one clear job and only the access it needs, require human approval for sensitive actions, define structured handoffs, set limits on steps and retries, and log every agent action so you can review what happened.
Navy GrtLabs graphic of an AI search answer citing a business website as its first source, illustrating answer engine optimization.
AI Search and SEO: How to Get Cited in ChatGPT, Perplexity and AI Overviews
AI Search and SEO: How to Get Cited in ChatGPT, Perplexity and AI Overviews 1024 576 Nadeem Shaikh

Answer engine optimization (AEO) is the work of making your content easy for AI search tools such as ChatGPT, Perplexity and Google’s AI Overviews to find, understand and cite. In practice it means answering real buyer questions directly near the top of the page, structuring pages with clear headings and FAQ schema, making your business details consistent everywhere, letting AI crawlers reach your site, and publishing original content worth quoting. It builds on good SEO rather than replacing it.

More buyers now ask an AI tool a question before they ever click a search result. When that tool answers, it names a few sources. This guide covers what you can do so one of those sources is you, and how to tell whether it is working.

What is answer engine optimization (AEO)?

Traditional SEO aims to rank a page in a list of blue links. AEO aims to get your content used inside the answer itself: quoted, summarized or linked as a source when someone asks an AI assistant or sees an AI-generated summary at the top of a search page.

The two overlap heavily. AI search tools still have to find your pages, and many of them lean on regular search indexes to decide what to read. A slow, poorly structured site that does not rank well is unlikely to be cited either. What AEO adds is a sharper focus on the questions buyers ask, on answers that make sense when lifted out of the page, and on signals that help a machine trust who you are.

In broad terms, an AI search tool takes the question, retrieves pages that look relevant, and writes an answer from them, often with links. If you have read our guide to retrieval-augmented generation, it is the same idea applied to the open web. Your job is to make your page the easiest good source to retrieve and quote.

Step 1: Structure answers so they are easy to lift

AI tools pull passages, not whole pages. A passage that answers the question on its own is far more useful to them than a clever introduction that gets to the point in paragraph five.

  • Lead with the answer. Put a direct two-to-four sentence answer right under the heading, then add detail.
  • Use the question as the heading. Headings such as “How long does a website redesign take?” match how people phrase prompts.
  • One topic per section. Keep each H2 focused, so a single section can stand alone.
  • Use lists and steps for processes, comparisons and checklists. They are easy to scan for people and machines.
  • Write plainly. Define terms the first time you use them and avoid vague marketing phrases that say nothing a tool could quote.
  • Keep one H1 per page and a logical heading order underneath it.

Step 2: Add FAQ content and schema markup

A short FAQ at the end of a service page or article covers the follow-up questions buyers ask. Keep each answer to a few sentences that stand alone, and use questions real customers ask, from sales calls, support emails and Search Console queries.

Then add structured data. Schema.org markup in JSON-LD tells machines what a page is about in a format they do not have to guess at. Useful types for most businesses include:

  • Organization or LocalBusiness on your homepage or contact page, with your name, address, phone, logo and social profiles.
  • Service on service pages, describing what you offer and where.
  • Article on blog posts, with the author and dates.
  • FAQPage for genuine question-and-answer sections.
  • BreadcrumbList so the place of each page in your site is clear.

Schema does not guarantee a citation, and the markup must match what is visible on the page. Its value is reducing ambiguity, which is exactly what AI tools need. Test it with Google’s Rich Results Test or the Schema Markup Validator before you publish.

Step 3: Make your business a clear entity

AI tools try to work out who a business is, what it does and whether other sources agree. If your name, services and location look different on every site, the picture gets blurry. Make it sharp:

  • Use the same business name, address and phone number on your website, Google Business Profile, LinkedIn and directory listings.
  • Describe your services in the same words across your site and profiles, so the connection between your brand and each service is obvious.
  • Link your website to your official social profiles, and link those profiles back to your website.
  • Add a real About page and author information, so readers and machines can see who stands behind the content.

For local businesses this overlaps with local SEO. A complete, accurate business profile helps both map results and AI answers to questions such as “who offers this service near me?”

Step 4: Let AI crawlers reach your content

If an AI tool cannot fetch your page, it cannot cite it. Check the technical basics:

  • Review robots.txt. Many AI tools use their own crawlers, such as OpenAI’s OAI-SearchBot and GPTBot, PerplexityBot, and Google-Extended for some Google AI uses. Decide deliberately which you allow rather than blocking them by accident. Google’s AI Overviews draw on regular Google Search crawling, so blocking Googlebot removes you from both.
  • Check your firewall and CDN. Security tools sometimes block bot traffic broadly. Make sure legitimate crawlers are not being turned away.
  • Put important text in the HTML. Content that only appears after heavy JavaScript runs, or is locked inside images and PDFs, is harder for crawlers to read.
  • Keep pages fast and indexable. Clean URLs, an up-to-date XML sitemap, correct canonical tags and no accidental noindex tags.

A clean site structure is the foundation here. If your current site makes this hard, our comparison of custom websites and templates explains when a rebuild is worth it.

Step 5: Publish original content worth citing

AI answers tend to blend many sources together. When ten sites say the same generic thing, there is little reason to name yours. Content that is cited usually adds something others do not have:

  • Your own process, explained step by step, with the trade-offs you have learned from real projects.
  • Original data, such as survey results or anonymized patterns from your own work, with the method explained.
  • Clear definitions and comparisons in your field, kept accurate and up to date.
  • Specific, honest answers to buyer questions about scope, timelines and how you work.
  • Dated pages that you review and refresh when facts change.

Do not invent numbers or quotes to look authoritative. Inaccurate claims hurt trust with readers, and a wrong statement repeated by an AI tool under your name is worse than not being cited at all.

Step 6: Measure AI referrals and citations

AEO is newer than SEO and the measurement tools are still catching up, so combine a few signals:

  • Referral traffic in analytics. In Google Analytics 4, look at sessions by source for referrers such as chatgpt.com, perplexity.ai, copilot.microsoft.com and gemini.google.com. Some tools also add a utm_source tag to links they send.
  • Search Console. AI Overviews traffic is counted within regular web search results, so watch impressions and clicks for the queries your answer pages target.
  • Manual prompt checks. Keep a list of the questions buyers ask, run them in the main AI tools each month, and note whether you are cited and which page is used.
  • Ask new leads. Add “How did you hear about us?” to your contact form, with an AI assistant option.
  • Track conversions, not only visits. A handful of AI referrals that turn into calls matters more than a spike in traffic that never converts.

Answers change from day to day and differ by user, so look for trends over weeks rather than reacting to a single result.

How GrtLabs can help

Our SEO and digital marketing team in Houston combines technical SEO, content, local search, social media and paid advertising into one plan. We start with a website SEO audit of your technical health, page structure, content and search visibility, then fix on-page issues such as titles, headings and internal links, write original content that answers your buyers’ questions, and improve your business profile and local citations. We track traffic, rankings, leads and conversions, and share plain-language reports.

If you want your own site to answer visitor questions the same way AI search does, our AI assistants answer from your approved content and pass qualified leads to your team.

Want to know how your site looks to AI search? Contact our Houston team for a website review, or see our SEO and digital marketing services.

Frequently asked questions

What is answer engine optimization (AEO)?

Answer engine optimization is the practice of making your content easy for AI search tools such as ChatGPT, Perplexity and Google AI Overviews to find, understand and cite. It focuses on direct answers to real questions, clear page structure, schema markup, consistent business information and crawlable pages.

Is AEO different from SEO?

AEO builds on SEO rather than replacing it. SEO aims to rank pages in search results, while AEO aims to get your content quoted or linked inside AI-generated answers. Both depend on a fast, crawlable site with useful, well-structured content.

How can I tell if ChatGPT or Perplexity is citing my website?

Check referral traffic in your analytics for sources such as chatgpt.com and perplexity.ai, run the questions your buyers ask in those tools each month and note which pages are cited, and ask new leads how they found you.

Should I block AI crawlers from my website?

It depends on your goals. If you want AI search tools to cite your pages, allow their search crawlers in robots.txt and your firewall. You can still block crawlers used only for model training if you prefer, so review each one deliberately.

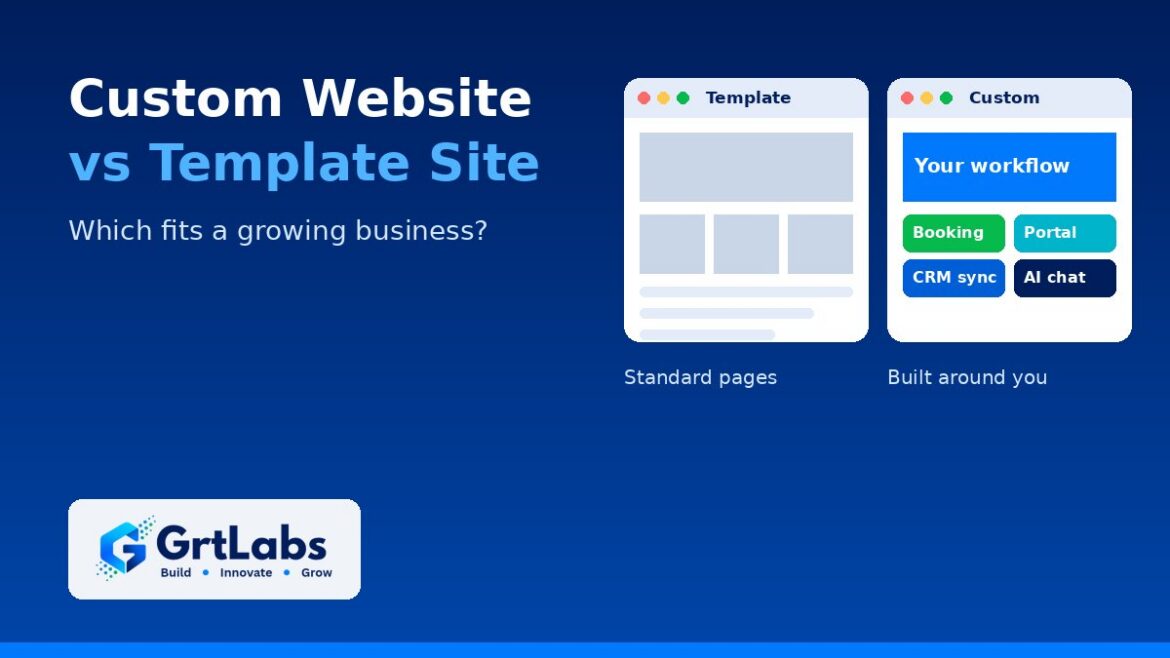
Navy GrtLabs graphic comparing a template website with a custom website built around business workflows
Custom Website vs Template Site: Which Fits a Growing Business?
Custom Website vs Template Site: Which Fits a Growing Business? 1024 576 Nadeem Shaikh

A template website is enough when you need a simple, good-looking site fast and your needs match what the template already does: a few pages, a contact form, a blog. A custom website makes sense once your site has to do real work for the business, such as booking, quoting, customer portals, connections to your CRM or ERP, or AI features, or when the template starts fighting every change you want. Many growing companies land in the middle: a solid CMS or store platform with custom pieces built only where they pay off.

The choice is not really about looks. Both can look professional. It is about what the site has to do, who will maintain it, and how much the workarounds are already costing you. Here is how to tell which fits.

What counts as a template site, and what counts as custom?

A template site starts from a pre-built theme on a website builder or a CMS such as WordPress, Shopify or BigCommerce. You swap in your logo, text and photos, and you work within the layouts and features the theme and its plugins already offer.

A custom website is designed and built around your business. The layout, content structure and features are planned for your buyers and your workflows. It can still run on a CMS your team edits every day; “custom” means the parts that matter are built for you, not that everything is hand-coded from scratch.

Custom website vs template: a side-by-side view

  • Speed to launch: templates are faster, because the design and features already exist. Custom work needs discovery, design and build time.
  • Upfront cost: templates cost less to start. A custom build costs more upfront, and the price depends on pages, features and integrations.
  • Fit to your business: a template fits businesses whose needs look like everyone else’s. Custom fits when your process, offer or buyers are different.
  • Integrations: templates rely on whatever plugins or apps exist. Custom builds can connect directly to your CRM, payment gateway, inventory or ERP through their APIs.
  • Performance: many themes load features you never use, and plugin stacking can slow pages down. A custom build can ship only what the site needs.
  • Security and upkeep: every extra plugin is one more thing to update and review. Custom code also needs maintenance, so plan for it either way.
  • Room to grow: templates are easy to start and harder to stretch. Custom is slower to start and easier to extend in the direction you need.

When is a template website enough?

A template is often the right call, and there is no reason to pay for custom work you do not need. It is usually enough when:

  • You are a new or small business that needs a credible web presence quickly.
  • The site is mostly informational: who you are, what you do, how to reach you.
  • Your features are standard: a contact form, a blog, a simple store with a normal checkout.
  • You have a small budget, and the money is better spent on content and marketing for now.
  • You can live with the theme’s layouts without heavy changes.

If that describes you, pick a well-supported theme, keep plugins to a minimum, and put your effort into clear pages and useful content.

Signs you have outgrown your template

Templates rarely fail all at once. They get slower and harder to work with until the workarounds cost more than a proper build. Watch for these signs:

  • Every change is a fight. Small layout or content changes need a developer, custom CSS hacks or another plugin.
  • Your team re-types data. Form submissions, orders or bookings get copied by hand into your CRM, ERP or spreadsheets.
  • The site is slow on phones. Too many plugins and unused theme features weigh down every page.
  • You need a real workflow. Customer logins, a quote builder, booking with payments, dashboards or an admin panel tied to your own data.
  • Plugins conflict or fall behind on updates, and nobody is sure what is safe to change.
  • You look like your competitors. The same theme, the same layout, and nothing that shows why you are different.
  • You want AI features, such as an assistant that answers from your own content, and the template has no clean way to add them.

Where AI fits in the decision

More businesses now want their website to do more than display pages. Common requests include an on-site AI assistant that answers questions from approved content and hands off to a person when it should, natural-language search across product or support documents, and automatic routing of form submissions and orders into back-office systems.

These features depend on two things a basic template rarely gives you: clean, well-structured content, and a site that can connect securely to your data and other systems. A plugin chatbot bolted onto a template can answer simple questions, but if you need answers grounded in your own documents, access controls or hand-offs to your CRM, you are into custom territory. Our guides to retrieval-augmented generation and AI workflow automation explain how those pieces work.

A clear, well-structured site also helps with search, including AI-generated answers: one H1 per page, logical headings, readable URLs and direct answers to the questions buyers ask.

The middle path: a platform plus custom pieces

For many growing businesses, the best answer is not a pure template or a from-scratch build. It is a proven platform with custom work only where it pays off:

  • A content management system your team can edit, with a custom design and page structure built around how your buyers decide.
  • A Shopify, BigCommerce or WooCommerce store with custom features and integrations that off-the-shelf themes do not cover.
  • A marketing site on a CMS, plus a separate custom web app for the portal, booking or dashboard your customers log into.
  • Integrations that move form, order and customer data into the systems you already use, so nobody re-types it.

This keeps everyday editing easy and costs under control, while the parts that make you money work the way your business does.

Questions to ask before you decide

  • What does the site need to do in the next two to three years, not just at launch?
  • Which systems must it connect to: CRM, payments, inventory, ERP, scheduling?
  • Who will update it day to day, and how comfortable are they with the editor?
  • Which manual steps around the website cost your team time every week?
  • Do you plan to add AI features, such as an assistant or smart search?
  • What would it cost you if the site were slow, hacked or down for a day?

If most answers point to standard needs, start with a template. If several point to integrations, workflows or AI, scope a custom or hybrid build before you spend more time on workarounds.

How GrtLabs approaches custom websites

Our custom website development team in Houston builds business websites, web applications and portals, ecommerce stores on Shopify, BigCommerce and WooCommerce, integrations and redesigns. Every build includes mobile-friendly layouts, attention to performance, a security review, a search-friendly structure and an editing setup your team can use without calling a developer for every change. We recommend CMS, store platform or custom code during discovery and explain the trade-offs, then give you a written scope and estimate before work begins.

When the site needs to do more, our AI Factory adds AI assistants grounded in your content and AI automation that routes submissions and orders into your systems, and our digital marketing team brings the right visitors to the new site.

Not sure whether your template still fits? Talk to our Houston team about what your site needs to do, or see how we build custom websites.

Frequently asked questions

When is a template website enough?

A template website is enough when you need a simple site quickly, your content is mostly informational, and your features are standard, such as a contact form, a blog or a simple store. If you can live with the theme’s layouts, a template is often the most sensible choice.

Is a custom website better for SEO than a template?

Not automatically. Search engines care about useful content, fast pages, a clean heading structure and readable URLs. A template can do this well. Custom builds help when a heavy theme or plugin stack slows pages down, or when you need page structures the template cannot support.

Can I start with a template and move to a custom website later?

Yes, and many businesses do. Keep your content well organized and your URLs readable, so a later rebuild can keep the pages that already work and redirect anything that moves.

How much does a custom website cost?

It depends on the number of pages, the features and the integrations involved. A good development partner gives you a written scope and estimate after a short discovery conversation, so you know what to expect before work begins.

Navy GrtLabs graphic showing a short two-step online form drafted with AI, for a guide on how to create an online form
How to Create an Online Form People Actually Finish (With AI)
How to Create an Online Form People Actually Finish (With AI) 1024 576 Nadeem Shaikh

To create an online form people actually finish, decide the one job the form has to do, ask only the questions you will really use, put the easy ones first, hide questions that do not apply with conditional logic, split anything long into short steps, and test it on a phone before you share it. AI form builders now make the first draft fast: you describe the form in plain words and get a set of suggested fields to edit. The real work is still cutting it down.

Most forms fail for the same reasons: too many questions, questions that do not apply, and a layout that is painful on a phone. Here is a step-by-step way to build one that gets completed, whether it is a contact form, quote request, registration or client intake form.

Step 1: Write down the form’s one job

Before you add a field, finish this sentence: “This form exists so that we can ___.” Book a call, send a quote, register an attendee. If you cannot finish it in a few words, the form is trying to do too much.

Step 2: Draft the form with AI, or by hand

You can start from a blank page or a template, but with an AI form builder you can also describe the form in a sentence or two, for example: “A quote request form for a cleaning company. Ask for name, work email, building type, square footage and start date.” The AI turns that into a draft with suggested fields, which you then edit.

Two tips make AI drafts better:

  • Say who the form is for and what you need to decide. “Qualify leads for a quote” gets better suggested fields than “contact form”.
  • Treat every AI-suggested field as a proposal, not a decision. AI tends to add fields that are nice to have. Run each one through the cut test in Step 3.

Step 3: Cut every question you will not use

This is the step that matters most for completion. For each field, ask: “If we removed this, would we lose something we act on?” If the honest answer is no, delete it. Common cuts:

  • Details you can get later. A full mailing address on a first inquiry, a company size range nobody reads.
  • Questions you can answer yourself. “How did you hear about us?” can often be captured with hidden fields that read campaign values from the link, so the person never has to type it.
  • Duplicate asks, such as a confirm-email field on a simple form.
  • Rarely used optional fields that only crowd the screen.

Step 4: Ask in the right order, in plain words

Start with easy questions such as name and email, and save harder or more personal ones for later. Then:

  • Write labels as plain questions (“When do you want to start?”) instead of internal jargon.
  • Use the right field type: a dropdown or radio buttons for fixed choices, a date picker for dates, an email field for email so the phone shows the right keyboard.
  • Put short, related fields side by side so the form looks shorter.
  • Mark what is required, and keep required fields to the ones you truly need.
  • Add a hint only where people are likely to get stuck.

Step 5: Use conditional logic so people only see what applies

Conditional logic shows or hides fields, or skips pages, based on earlier answers. A homeowner does not need to see the commercial building questions. Logic lets one form serve several kinds of people while each person sees a short, relevant version.

Step 6: Split long forms into short steps

Some forms have to be long, such as job applications or client intake. Use page breaks to split them into short steps with a clear theme each, such as “About you” and “Your project”. Put the contact details on the first step, so if someone stops partway you still know who they were.

Step 7: Make it easy on a phone

Many people will open your form from a link on their phone. Preview it at phone width before you share it. Check that buttons are easy to tap and that uploads and signatures work. Use built-in validation for email and phone format, with error messages that say what to fix.

Step 8: Keep spam out without punishing real people

Heavy protection on every form adds friction for real visitors. Keep protection running quietly in the background, watching for bursts of submissions from the same address, and turn on a CAPTCHA when a form starts attracting abuse, instead of making everyone solve one from day one.

Step 9: Publish, then measure and improve

Share the form by link, or embed it on your website so people do not have to leave the page. Then add analytics or ad tracking and compare how many people view the form with how many submit it. If a form gets views but few submissions, look first at its length, the required fields and how it behaves on a phone.

How long should an online form be?

As short as its job allows. A contact or newsletter form usually needs only a few fields. A quote request needs enough detail to price the work, and no more. A job application or client intake form can be long, as long as it is split into steps, uses logic to hide what does not apply and asks for contact details first. There is no magic number of fields; the right length is the shortest form that still gives your team everything it needs to act on the submission.

A checklist before you publish

  • The form’s one job is written down, and every field supports it.
  • Every AI-suggested field has been reviewed, and unused ones are removed.
  • Easy questions come first; labels are plain questions.
  • Conditional logic hides questions that do not apply.
  • Long forms are split into steps, with contact details on step one.
  • The form has been tested at phone width, including uploads and signatures.
  • Tracking is in place so you can compare views with submissions.
  • Someone owns the submissions and knows what to do with each one.

When a form is only the first step

The time often goes after the form: re-keying answers into a CRM or ERP, checking uploads, routing requests. Webhooks can send each submission straight to your other systems, and AI can read attached invoices, contracts or IDs and turn them into clean data, as we explain in our guide to intelligent document processing. If you are deciding which back-office steps to automate first, see AI workflow automation, or look at how our AI Automation team connects the systems you already use.

Build your next form with GRTforms

GRTforms is the online form builder made by GrtLabs. With Create with AI, you describe the form you need in plain words, and GRTforms drafts the fields, pages and theme in the language you choose (English, Spanish, French, German or Portuguese), then opens the draft in a drag-and-drop builder so you can edit it before you publish. Only your prompt is sent to the AI, never your respondents’ answers. You can even try it at grtforms.com/try without an account.

The builder covers the steps above: conditional logic, multi-page forms, required fields and validation, hidden fields for UTM and campaign values, side-by-side half-width fields, file uploads, e-signatures and star ratings. Share it by link or embed, add GA4, Google Tag Manager, Meta Pixel or HubSpot tracking, send submissions to other tools with webhooks, and keep spam out with abuse alerts, IP blocking and Cloudflare Turnstile CAPTCHA. It is free to start, with no credit card required.

Ready to build a form people finish? See GRTforms, or if your forms need to feed custom software or an AI workflow, talk to our Houston team.

Frequently asked questions

How long should an online form be?

As short as its job allows. Ask only for information your team will use to act on the submission. Simple contact forms need a few fields; longer forms such as job applications or client intake should be split into short steps, with logic that hides questions that do not apply.

Can AI create an online form for me?

Yes. AI form builders such as GRTforms Create with AI let you describe the form in plain words and get a draft with suggested fields and pages. Review every suggested field, remove the ones you will not use, and edit the draft before you publish.

How do I get more people to finish my online form?

Cut fields you do not need, put easy questions first, use conditional logic to hide questions that do not apply, split long forms into steps, make sure it works well on a phone, and write error messages that say what to fix.

Should I embed a form on my website or share a link?

Both work. Embedding keeps visitors on your website, which suits contact and quote forms. A public link is easier to share by email, text or social media. Many form builders, including GRTforms, give you both from the same form.

Navy GrtLabs graphic with a vendor checklist for choosing an AI development company in Houston
Choosing an AI Development Company in Houston: What to Ask Before You Sign
Choosing an AI Development Company in Houston: What to Ask Before You Sign 1024 576 Nadeem Shaikh

Before you sign with an AI development company in Houston, get clear, written answers on five things: which problem they will solve first, where your data will live, who owns what they build, how they will prove it works on your real data, and who runs it after launch. A good partner answers all five in plain words. A vague answer to any of them is a warning sign, no matter how good the demo looked.

Plenty of firms in Houston now offer AI. The hard part is telling a team that can ship a working system inside your business from one that can only show a polished prototype. The questions below work for any vendor, local or remote, and they are the same questions we expect buyers to ask us.

1. Start with the problem, not the technology

The first conversation should be about your process, not about model names. Ask:

  • What problem would you solve first, and how will we measure it? Hours saved, errors avoided, faster replies to customers: something you can count.
  • Have you built something like this before, and can you show it? Ask for a walkthrough of real work, not slides.
  • Would you tell us if AI is the wrong tool? Some problems are better solved with a simple automation, a report or a process change.

A good sign is a vendor who asks about your documents, systems and exceptions before proposing anything. A warning sign is a proposal that leads with “AI transformation” and never names a specific workflow. If you are still deciding between buying a tool and building one, our guide to off-the-shelf AI vs custom AI can help.

2. Ask where your data goes

This is the question that matters most for companies in healthcare, energy, finance and any business with customer records. Ask:

  • Will our data stay inside our own AWS or Azure account, or pass through yours?
  • Which model providers will see our prompts and documents, and do their terms allow them to train on that data?
  • Will the AI respect our existing permissions, so nobody sees documents they could not already open?
  • Can it run on a self-hosted model if our privacy rules rule out outside AI services?
  • How will you protect it against prompt injection and other misuse?

If the system will answer questions from your documents, ask how retrieval works and how answers cite their sources. Our RAG explainer covers what good looks like.

3. Ask who owns what you pay for

Ownership gets messy when it is not written down. Ask who owns the code, prompts, configuration, data pipelines, any fine-tuned models and the documentation. Then ask the follow-up: if we part ways, can another team pick this up and run it? Watch for systems built on a vendor’s own closed platform that you can only keep using by paying them. Whatever the answer, put it in the contract.

4. Ask how they will prove it works

A demo on the vendor’s sample data proves very little. Ask:

  • Will the proof of concept use our real documents and data?
  • What does success look like, agreed before the build starts? For example, an accuracy target on a test set, or time saved per task.
  • How do you test answers, and where do people review the output before it is trusted?
  • What happens if the proof of concept misses the target?

A short discovery phase before any build is the cleanest way to get these answers. Our AI readiness assessment guide lists what that phase should cover.

5. Ask how it runs after launch

AI systems need care after go-live: models change, documents change and usage grows. Ask who monitors quality and errors, how cloud and model costs are tracked and capped, how model updates are tested, and who you call when something breaks. For agents that take actions, ask whether every action is logged so you can review it later, as we describe in AI agent audit trails. Our LLMOps guide covers the day-to-day side in more detail.

Also ask what handoff looks like: documentation, training for your team, and whether you can run it yourselves if you choose to.

6. Ask about cost the right way

Any honest vendor will struggle to quote a full AI build before seeing your data and systems. Instead of asking for one number on the first call, ask how pricing is structured (a fixed discovery phase, time and materials, a monthly support plan), what drives ongoing cloud and model usage costs and who pays them, and what support includes. Then ask for a written estimate once discovery is done, when it can be based on real scope.

Red flags to watch for

  • Accuracy or savings promised before anyone has looked at your data.
  • No mention of human review where a mistake would be costly.
  • Unclear answers about where your data goes or which AI providers see it.
  • A closed platform with no way to take your system elsewhere.
  • Demos only on the vendor’s own sample data.
  • No plan for monitoring, support or handoff after launch.

Does it matter if the AI company is in Houston?

Local is not a reason on its own to pick a vendor; the answers above matter more. But a Houston-based team does make some things easier: discovery workshops can happen in person at your office, meetings and fixes happen on Central Time, and the team is more likely to know the documents and systems common in Houston industries such as energy, healthcare, construction and logistics. A remote team that answers every question well is still a better choice than a local one that does not.

A checklist to bring to your first call

  • Which problem will you solve first, and how will we measure it?
  • Where will our data live, and which AI providers will see it?
  • Who owns the code, prompts, pipelines and models?
  • Will the proof of concept use our real data, with success agreed up front?
  • Who monitors, supports and pays for running it after launch?
  • How is pricing structured, and when will we get a written estimate?

How GrtLabs answers these questions

GrtLabs is a Houston AI lab and software company at 10101 Southwest Fwy #431. We usually start with AI Discovery, a focused 2–3 week engagement where we review your data, systems and processes, rank use cases by value and feasibility, and give you build or no-build recommendations with a roadmap that is yours whether or not you build with us. When we build, we deploy inside your own AWS or Azure account with access controls you own, plus monitoring, logging and cost budgets, and we document the system and train your team to run it. See what we build and how an engagement works on our AI development company in Houston page.

Comparing AI vendors in Houston? Bring this checklist to us too. Talk to our team about your first use case, or start with AI Discovery.

Frequently asked questions

What should a Houston business ask an AI development company before signing?

Ask which problem they will solve first and how it will be measured, where your data will live and which AI providers will see it, who owns the code and models, how the proof of concept will be tested on your real data, and who monitors and supports the system after launch. Get the answers in writing.

How long does it take to know if an AI project will work?

Usually a few weeks. A short discovery phase picks the right first use case, and a proof of concept on your own data shows whether it meets the success target you agreed up front. At GrtLabs, AI Discovery typically takes 2–3 weeks.

How much does it cost to hire an AI development company?

It depends on the use case, the data involved and the systems that need to connect, so an honest vendor will not quote a full build before seeing them. Ask how pricing is structured, what ongoing cloud and model costs to expect, and for a written estimate after discovery.

Do I need a local AI development company, or can I hire a remote one?

Either can work. A local Houston team makes in-person workshops and same-time-zone support easier, but clear answers on data, ownership, testing and support matter more than location.

Navy GrtLabs graphic comparing two clouds labeled Bedrock and Azure OpenAI.
AWS Bedrock vs Azure OpenAI: How to Choose a Cloud AI Platform
AWS Bedrock vs Azure OpenAI: How to Choose a Cloud AI Platform 1024 576 Nadeem Shaikh

Choose Amazon Bedrock if your systems and data already live on AWS and you want one API for models from several providers. Choose Azure OpenAI if you run on Microsoft Azure and Microsoft 365, or you specifically want OpenAI’s GPT models with Microsoft’s security and identity tools. For most companies, the cloud you already use matters more than any single model, because that is where your data, access rules and billing already sit.

Both services let a business use large language models through a managed cloud service instead of a consumer chatbot. Both keep your data inside your cloud account’s controls, and both can power assistants, document search and automation. The differences are in which models you get, how each fits your existing stack, and how your team will build and run things day to day. This guide walks through those differences in plain words.

What Amazon Bedrock is

Amazon Bedrock is AWS’s managed service for foundation models. Instead of hosting models yourself, you call them through one AWS API. Bedrock offers models from several companies, including Anthropic’s Claude, Meta’s Llama, Mistral and Amazon’s own models, so you can compare and switch models without changing clouds.

Around the models, Bedrock adds building blocks such as knowledge bases for answering from your own documents, agents that can call your systems, and guardrails for filtering what goes in and out. Access is controlled with the same AWS identity and networking tools your team may already use.

What Azure OpenAI is

Azure OpenAI is Microsoft’s service for running OpenAI’s models, such as the GPT family, inside Azure. It is now part of Microsoft’s broader AI Foundry platform, which also lists models from other providers. You get the OpenAI models many people already know from ChatGPT, but under your company’s Azure account, with Microsoft Entra ID for sign-in and access, private networking options and Azure’s content filters.

For document search, teams usually pair it with Azure AI Search. If your company runs on Microsoft 365, Teams and SharePoint, Azure tends to connect to those tools with less custom work.

AWS Bedrock vs Azure OpenAI: the main differences

  • Model choice. Bedrock is built around many model providers behind one API. Azure OpenAI centers on OpenAI’s models, with other models available through the wider Foundry catalog. Both catalogs change often, so check the current list for the exact models and regions you need.
  • Fit with your stack. If your apps, databases and files are on AWS, Bedrock keeps everything close. If you run on Azure and Microsoft 365, Azure OpenAI fits more naturally.
  • Identity and security. Bedrock uses AWS IAM and VPC networking. Azure OpenAI uses Entra ID and Azure networking. Neither is weaker; the better one is the one your team already manages well.
  • Building blocks for RAG and agents. Both offer managed ways to ground answers in your documents and to build agents that take actions. The tools differ in setup and detail, so a short prototype on your own data tells you more than a feature list.
  • Pricing and capacity. Both mainly charge by usage (tokens in and out), with options for reserved capacity at higher volumes. Rates vary by model and region and change over time, so price your real workload on each provider’s current pricing page rather than relying on old comparisons.
  • Data handling. Both providers state that your prompts and outputs are not used to train the underlying models. Read the current terms for your region and compliance needs before you send sensitive data.

When Amazon Bedrock is the better fit

  • Your main systems and data are already on AWS
  • You want to test several model families and keep the option to switch
  • You plan to build RAG over your company documents stored in AWS
  • Your team already knows IAM, VPCs and AWS cost tools

When Azure OpenAI is the better fit

  • Your company runs on Azure, Microsoft 365, Teams or SharePoint
  • You specifically want OpenAI’s models with enterprise controls
  • Your security team manages access through Microsoft Entra ID
  • You already have an Azure agreement and want AI spend on the same bill

Can a company use both?

Yes, and some do. A common pattern is to put a thin layer in your own code between your app and the model provider, so the app does not care which cloud answers. That lets you route each task to the model that does it best, keep a backup if one service has an outage, and compare cost over time. The trade-off is extra setup: two sets of access rules, two bills and two sets of logs to watch. Our post on LLMOps covers how to keep that monitoring under control.

How to decide in four steps

  1. Start from your current cloud. If one cloud already holds most of your data and apps, begin there unless a model you need is missing.
  2. List the models you need. Confirm they are available on each platform in the regions where your data must stay.
  3. Run the same test on both. Use real examples from your business, with known good answers, and compare accuracy, speed and cost per request.
  4. Check security and compliance. Confirm identity, networking, logging and data terms meet your requirements before anything goes to production.

If your use case is narrow and high-volume, also test a smaller model. Our guide to small language models explains when a smaller model is the better choice.

How GrtLabs can help

GrtLabs is a Houston AI lab that works in whichever cloud you already use, or helps you choose. Through our AWS and Azure AI services, we help with architecture and service selection, model hosting, RAG over your documents, and moving a working prototype into a secure, monitored production setup inside your own cloud account, with access controls you own and budgets that keep cost in check. If you are still deciding where AI fits, start with AI Discovery.

Talk to GrtLabs about choosing your cloud AI platform.

FAQ

What is the difference between AWS Bedrock and Azure OpenAI?

Amazon Bedrock is AWS’s managed service that gives one API to foundation models from several providers. Azure OpenAI is Microsoft’s service for running OpenAI’s GPT models inside Azure. Bedrock is built around model choice on AWS, and Azure OpenAI is built around OpenAI models with Microsoft’s security and identity tools.

Which is better for a business, Bedrock or Azure OpenAI?

Neither is better for everyone. The best choice is usually the cloud that already holds your data and apps, as long as it offers the models you need. Test both on your own examples if you are unsure.

Can a company use both AWS and Azure for AI?

Yes. Many teams add a small layer in their own code so an app can call either provider. This lets them route tasks to the best model and keep a backup, at the cost of managing two sets of access rules, bills and logs.

Do AWS Bedrock and Azure OpenAI use my data to train models?

Both providers state that customer prompts and outputs are not used to train the underlying models. Check each provider’s current data terms for your region and compliance needs before sending sensitive data.

Navy GrtLabs graphic with a large and a small computer chip and the title Small Language Models
Small Language Models: When a Smaller AI Model Is the Better Business Choice
Small Language Models: When a Smaller AI Model Is the Better Business Choice 1024 576 Nadeem Shaikh

A small language model (SLM) is an AI language model that is much smaller than the giant models behind tools like ChatGPT, small enough to run on one server, a laptop, or even a phone. For narrow, repeatable business tasks, a well-chosen small model can be faster, cheaper to run, and easier to keep inside your own environment than a large one, though it gives up some broad knowledge and reasoning.

Most companies start their AI work with the biggest model they can get. That makes sense for a prototype. But once a use case is clear and the volume grows, many teams find they are paying a large model to do a small job. This guide explains what small language models are, where they fit, where they don’t, and how to decide.

What counts as a small language model

There is no official size cutoff. “Small” is relative: these models have far fewer parameters (the learned values inside the model) than the largest frontier models, so they need less memory and less computing power to run. Several open-weight model families, such as Llama, Mistral, Gemma, and Phi, publish smaller versions, and the major cloud platforms offer smaller models alongside their large ones.

In practice, people use the term for models that can:

  • Run on a single GPU server, or on ordinary hardware without a GPU for some tasks
  • Run on a device such as a laptop or phone, with no internet connection
  • Answer quickly enough for high-volume, real-time work

Small vs large language models: the real trade-offs

Neither size is “better.” They are good at different things.

  • Breadth of knowledge. Large models know more about the world and handle open-ended questions better. Small models know less, so they rely more on the context you give them.
  • Reasoning. Large models usually do better on multi-step reasoning, long documents, and tricky instructions. Small models can struggle when a task needs many steps or judgment calls.
  • Speed. Small models usually answer faster, which matters for chat, search, and anything a user waits on.
  • Running cost. Fewer parameters means less compute per request. At high volume, that difference shows up on the bill.
  • Where it runs. A small model can run in your own cloud account, in your data center, or on a device. That gives you more control over where data goes.
  • Customization. Small models are cheaper and faster to fine-tune on your own examples, so they can become very good at one narrow job.

When a small language model is the better choice

Small models shine when the task is narrow, repeated often, and easy to check. Good fits include:

  • Classifying and routing. Sorting support tickets, emails, or documents into categories and sending them to the right team.
  • Pulling fields from text. Extracting names, dates, amounts, or order numbers from messages and forms.
  • Answering from your own documents. In a RAG system, the model gets the relevant passages handed to it, so it needs less built-in knowledge. A small model is often enough to write the answer.
  • Summaries and rewrites. Short summaries of tickets, calls, or notes in a fixed format.
  • Private or offline work. Situations where data should not leave your environment, or where the device may not have a connection.
  • Steps inside a bigger workflow. In AI workflow automation, many steps are simple. A small model can handle those while a larger model handles the hard ones.

When you still need a large model

Stick with a large model when:

  • Questions are open-ended and you cannot predict what users will ask
  • The task needs careful reasoning across many steps, such as planning in an agentic AI system
  • The work involves long or complex documents where missing a detail is costly
  • You are still exploring the use case and don’t yet know what “good” looks like

Many teams end up using both: a small model for the high-volume, simple requests and a large model for the cases the small one can’t handle well. A simple router decides which model gets each request.

How to decide: a practical test

Don’t choose a model on reputation. Test it on your own work:

  1. Write down the task clearly. What goes in, what should come out, and how you will know an answer is right.
  2. Build a test set. Collect real examples with known good answers, including the hard and unusual cases.
  3. Start with a large model as the baseline. Measure how often it gets the answers right on your test set.
  4. Try one or two small models on the same set. Compare accuracy, speed, and cost per request.
  5. Decide where the line is. If the small model is close enough on the cases that matter, use it. If it fails on certain types of requests, route only those to the large model.
  6. Keep testing after launch. Rerun the test set whenever you change prompts or models. Our post on LLMOps explains how to keep this running.

Running a small model: what to plan for

A small model you host yourself gives you control, but also responsibilities:

  • Hosting. Decide whether it runs as a managed cloud service, on your own servers, or on devices. Each has different setup and upkeep.
  • Security and access. The same rules apply as for any AI app: limit what data and tools it can reach, and log what it does.
  • Updates. New model versions come out often. Test each one on your set before switching.
  • Licenses. Open-weight models come with their own license terms. Check them for commercial use before you build on one.
  • Monitoring. Track accuracy, speed, and cost in production, just as you would for a large model.

How GrtLabs can help

GrtLabs, a Houston AI lab, helps teams pick the right models and cloud services, connect them to existing apps, and keep cost and access under control. Through our AWS and Azure AI services, we can test small and large models on your real tasks, design deployments inside your own cloud account, and move a working prototype into a secure, monitored production setup. If you are not sure where AI fits yet, our AI Discovery engagement is a good place to start.

Talk to GrtLabs about your use case.

FAQ

What is a small language model?

A small language model is an AI model that understands and writes text like a large language model, but with far fewer parameters. That makes it cheaper and faster to run and small enough to run on one server, a laptop, or a phone.

Are small language models as accurate as large ones?

Not in general. Large models know more and reason better on open-ended tasks. On a narrow, well-defined task, especially with good context or fine-tuning, a small model can come close enough to be the better choice. The only way to know is to test both on your own examples.

Can a small language model run without sending data to the cloud?

Yes. Because it needs less computing power, a small model can run in your own cloud account, on your own servers, or on a device, so prompts and data stay in an environment you control.

Should a business use a small model or a large model?

Use a small model for high-volume, narrow tasks that are easy to check, such as classifying, extracting fields, or answering from your documents. Use a large model for open-ended questions and complex reasoning. Many businesses use both and route each request to the right one.

Laptop showing a task board with a monitor dashboard ticket, beside screens with live charts and a mechanical keyboard
LLMOps Explained: How to Keep AI Apps Reliable After Launch
LLMOps Explained: How to Keep AI Apps Reliable After Launch 1024 576 Nadeem Shaikh

LLMOps is the set of practices that keeps an app built on a large language model (LLM) accurate, safe, and affordable after it goes live. It covers how you version prompts and models, test answers before each release, monitor quality and cost in production, and control who and what the AI can reach.

Most teams can get an AI prototype working in a few days. The harder part comes later: answers drift, a model update changes behavior, costs climb, and nobody can say why the assistant gave a wrong answer last Tuesday. LLMOps is how you stay ahead of those problems instead of finding out from your customers.

What LLMOps means in plain words

LLMOps stands for large language model operations. It borrows from DevOps and MLOps, but it focuses on the things that are different about LLM apps:

  • The output is text, not a number. You cannot check it with a simple pass or fail, so you need a way to judge whether answers are correct, grounded, and on-tone.
  • Prompts are code. A small wording change can change results, so prompts need versions, reviews, and tests like any other code.
  • The model can change under you. If you use a hosted model, the provider may release new versions or retire old ones. You need to know which version you run and test before you switch.
  • Every call costs money. Usage-based pricing means a busy week or a badly written prompt shows up on the bill.

Why LLM apps break after launch

An LLM app that worked in the demo can slip in production for a few common reasons:

  • Your data changes. If the app answers from your documents, as a RAG system does, new or outdated files change what it says.
  • Real users ask different questions. People phrase things in ways your test set never covered.
  • Prompts get edited without testing. A quick fix for one case quietly breaks three others.
  • Model versions change. A new version can be better overall and still worse on the questions your business cares about.
  • Attackers probe it. Prompt injection and data leakage attempts grow once an app is public. Our post on prompt injection protection covers the defenses.

The core parts of an LLMOps setup

1. Version prompts, models, and settings together

Keep prompts in source control next to the app code, and record the model name, version, and settings used for each release. When an answer goes wrong, you should be able to say exactly which prompt and model produced it, and roll back if needed.

2. Build an evaluation set before you ship

Collect real questions with known good answers, including the tricky ones and the ones the AI must refuse. Run the full set every time you change a prompt, a model, or the documents behind the app. Combine automated checks, such as whether the answer cites the right source, with a human review of a sample. If you cannot measure quality, you cannot tell whether a change helped.

3. Monitor quality, not just uptime

A server can be up while the AI gives bad answers. Track signals that point to quality: user thumbs up or down, questions the app could not answer, escalations to a person, and answers that did not use any retrieved source. Review a sample of real conversations on a regular schedule.

4. Log every step you may need to explain

Store the input, the retrieved context, the prompt version, the model, the output, and any tool calls the AI made. For AI agents that take actions, this record is essential. We cover what to capture in our guide to an AI agent audit trail. Decide up front how long to keep logs and how to protect personal data in them.

5. Control access and data

Give the AI only the data and tools it needs. Use identity and access controls so it can see what the person asking is allowed to see, and nothing more. Where data sensitivity matters, run the deployment inside your own cloud account rather than sending data to tools you do not control.

6. Watch cost from day one

Set budgets and alerts, track usage per feature, and review it regularly. Common savings come from shorter prompts, caching repeated answers, sending simple requests to a smaller model, and limiting how much context each call sends.

7. Release changes safely

Treat a prompt or model change like a software release: test it against the evaluation set, roll it out to a small share of users first, compare results, and keep a quick way to roll back.

Where LLMOps runs: AWS, Azure, or both

Both major clouds offer managed access to foundation models along with the logging, identity, and cost tools LLMOps depends on. The right choice is usually the cloud your company already uses, because your data, identity system, and security reviews are already there. What matters more than the vendor is that model hosting, retrieval over your data, pipelines, access controls, and cost monitoring are designed together rather than bolted on after launch.

When you need LLMOps, and how much

You do not need a large platform team on day one. Match the effort to the risk:

  • Internal pilot with a small group: version prompts, keep a basic evaluation set, log conversations, and set a budget alert.
  • Staff-facing tool in daily use: add quality monitoring, regular conversation reviews, and access controls tied to your identity system.
  • Customer-facing app or an agent that takes actions: add staged releases, a full audit trail, injection testing, and clear rules for when the AI hands off to a person. Our post on AI agent governance covers those rules.

Move your AI from prototype to production with GrtLabs

GrtLabs is a Houston AI lab that helps businesses run AI in production on AWS or Azure. We help you pick the right cloud services, wire them to your apps, and keep costs and access under control, including moving a working prototype into a secure, monitored production environment. See our AWS and Azure AI services or contact us to talk through your use case.

Frequently asked questions

What is LLMOps?

LLMOps, short for large language model operations, is the practice of running LLM-based apps reliably in production. It includes versioning prompts and models, testing answers against an evaluation set, monitoring quality and cost, logging what the AI did, and controlling its access to data and tools.

How is LLMOps different from MLOps?

MLOps focuses on training, deploying, and monitoring machine learning models, often ones you train yourself. LLMOps deals with apps built on large language models, which are often hosted by a provider, so the work centers on prompts, retrieval, output quality, safety, and usage cost rather than training.

Do small companies need LLMOps?

Yes, at a small scale. Even a pilot should version its prompts, keep a short evaluation set, log conversations, and set a budget alert. Add more as the app reaches more users or starts taking actions.

Can LLMOps run inside our own cloud account?

Yes. GrtLabs designs AWS and Azure AI deployments inside your cloud account with access controls you own, and sets up monitoring and budgets so you can see quality and cost.

Hand ticking boxes on a handwritten checklist in a notebook with sticky notes beside a data screen
AI Readiness Assessment: Questions to Answer Before Your First AI Project
AI Readiness Assessment: Questions to Answer Before Your First AI Project 1024 576 Nadeem Shaikh

An AI readiness assessment tells you, before you spend on a build, whether your goals, data, systems, and people can support AI, and which use case to start with. It ends with a ranked list of use cases, clear build or no-build calls, and a roadmap with one proof of concept to try first.

When a first AI project stalls, the cause is often not the model. It is that nobody agreed on the goal, the data was not where people thought it was, or no one owned the result. An AI readiness assessment puts those questions on the table early, while changing course is still cheap.

What an AI readiness assessment is

An AI readiness assessment is a short, structured review of your business before you commit to an AI build. It looks at four things: what you want to achieve, the processes involved, the data behind them, and the systems that would have to connect to anything you build. The output is a decision, not a demo: what is worth building first, and what is not.

A good assessment is just as useful when it tells you to wait, fix a process, or skip a use case.

Questions to answer before your first AI project

Work through these with the leaders who own the budget and the people who run the processes day to day. If you cannot answer a question, that gap is itself a finding.

Goals and value

  • What business problem are we solving? Name the process and the pain, such as slow intake or repeated manual checks.
  • How will we know it worked? Agree on the measure before anything is built: time saved, fewer errors, faster response, or less rework.
  • Who owns the outcome? One named person should be accountable for the result, not just the project plan.

Processes

  • Is the process written down? If the steps live only in one person’s head, document them first. AI on top of an unclear process makes the confusion faster.
  • Where does work stall today? Handoffs, re-keying, waiting on approvals, and searching for documents are common places to look.
  • What should stay with people? Decide early which steps need human judgment. Our post on AI workflow automation covers how to score processes and which ones to leave manual.

Data

  • Where does the data live? List the systems, file shares, inboxes, and spreadsheets the use case depends on.
  • Can we get to it? Data you cannot access through an export, API, or connector is a blocker, no matter how useful it looks.
  • Is it good enough to use? Check whether records are complete, current, and consistent. Perfect data is not required, but you need to know where the gaps are.
  • Is any of it sensitive? Personal, financial, or regulated data changes where the system can run and who can see the results.

Systems

  • What would the AI read from and write to? An answer that cannot reach the system where work happens is just another inbox.
  • Do we build, buy, or combine? Some needs are met by an existing tool; others need custom work on your own data. See off-the-shelf AI vs custom AI for how to weigh that choice.

People and risk

  • Who will use it, and will they trust it? Bring the people who run the process into the assessment, not just leadership.
  • What happens when it is wrong? Decide who reviews outputs, what gets escalated, and what the AI is never allowed to do on its own.
  • How will we govern it? Permissions, logging, and approval steps matter more as AI starts taking actions. Our guide to AI agent governance walks through the basics.

How to rank use cases: value and feasibility

Once you have a list of candidate use cases, rank each one on two questions:

  1. Value: If this worked, how much would it matter? Think about how often the process runs, how many people it touches, and what the current delays or errors cost the business.
  2. Feasibility: Can we actually build it now? Think about data access and quality, how clear the rules are, how easily the systems connect, and how much risk a wrong answer carries.

Use cases that score high on both are your first candidates. High value but low feasibility usually means groundwork comes first, such as cleaning a data source or documenting a process. Low value but easy to build rarely justifies the investment. Drop anything low on both.

Pick one use case for a proof of concept. A narrow, well-defined first project teaches you more than a broad one, and it gives leadership something concrete to judge.

Signs you are ready, and signs you are not yet

You are likely ready to start when:

  • A specific process has a clear owner and a measurable problem.
  • The data behind it is accessible, even if it needs some cleanup.
  • The people who run the process are willing to help shape and test the solution.
  • Leadership agrees on what success looks like and what a reasonable first step is.

You probably need groundwork first when:

  • The goal is “use AI” rather than a named business problem.
  • Nobody can say where the key data lives or who controls access to it.
  • The process changes every time someone different runs it.
  • There is no plan for who checks the output or handles mistakes.

What you should walk away with

A useful assessment ends with documents your team can act on, not just a slide of ideas. At GrtLabs, AI Discovery is a focused engagement of typically 2–3 weeks. We work with your leadership and process owners to understand your goals, data, and systems, and you get:

  • A discovery workshop with key stakeholders.
  • An AI readiness review of your data, systems, and processes.
  • A prioritized list of use cases ranked by value and feasibility.
  • Clear build or no-build recommendations.
  • A roadmap with a recommended proof of concept to start with.

The first project often points toward one of a few build types: agentic AI for multi-step work, AI automation and document intelligence for repetitive back-office tasks, RAG knowledge systems for answers grounded in your own documents, or AI assistants for staff and customers. The roadmap is yours to use however you choose.

Plan your AI Discovery with GrtLabs

GrtLabs is an AI lab that helps businesses decide what to build before they build it. If you know AI matters but are unsure where to start, which use cases to prioritize, or how to justify the investment, AI Discovery gives you a readiness review and a roadmap in a few weeks. Contact us to plan a Discovery.

Frequently asked questions

What does an AI readiness assessment cover?

An AI readiness assessment covers your business goals, the processes you want to improve, the data behind them, and the systems AI would need to connect to. It identifies where AI can create real value, ranks use cases by value and feasibility, gives build or no-build recommendations, and ends with a roadmap and a recommended first proof of concept.

How long does an AI readiness assessment take?

It depends on how many teams and processes are in scope. GrtLabs AI Discovery typically takes 2–3 weeks.

What do we need to provide for an AI readiness assessment?

Plan for access to key stakeholders for workshops and interviews, plus an overview of the relevant systems and data. Your data does not need to be perfect; finding the gaps is part of the assessment.

Do we have to build with the same company after the assessment?

No. With GrtLabs AI Discovery, the roadmap and recommendations are yours to use however you choose, whether you build with us, with another partner, or in-house.

Top-down marble desk with laptop clipboard checklist and pen
AI Workflow Automation: Which Business Processes to Automate First
AI Workflow Automation: Which Business Processes to Automate First 1024 576 Nadeem Shaikh

Automate first the processes that run often, follow clear rules, take structured inputs, and still leave room to route exceptions to a person — typically invoice and purchase-order intake, order routing with inventory sync, routine reports, and record validation. Leave rare judgment calls, poorly documented one-offs, and high-stakes exceptions under human ownership.

Teams lose hours to re-keying data, moving files, and checking the same fields by hand. That work is slow, error-prone, and hard to scale. AI workflow automation is how you remove that repetitive load from documents, orders, inventory, and back-office processes without throwing away the systems you already use.

What AI workflow automation is

AI workflow automation connects steps that people currently do by hand: read a document, classify it, pull the fields that matter, write them into another system, run a schedule, and flag anything that does not match the rules. On the GrtLabs Automations page, that delivery usually includes:

  • Process mapping and an automation plan so you know which steps to automate and which to leave with people.
  • Document extraction and classification with AI for invoices, POs, forms, and similar paperwork.
  • System-to-system integrations and scheduled workflows so data moves without copy-paste.
  • Exception handling, alerts, and dashboards so mismatches land with a person who has context.

When a document is the bottleneck, pair this with intelligent document processing. When a flow needs judgment across several steps, it can sit next to agentic AI. Document AI workloads can run on AWS or Azure AI when that fits your stack. You do not need to replace your ERP, CRM, or file tools — automations connect the tools you already use.

How to score which processes to automate first

Use a simple score before you build anything. Rate each process on five factors:

  1. Volume — How often does this run each day or week? High volume pays for itself faster.
  2. Rules clarity — Can a trained person explain the happy path in plain steps? If the rules live only in one person’s head, document them first.
  3. Data quality — Are inputs mostly structured or at least consistent (same form layouts, same field names, same file types)? Messy one-off emails are weaker candidates until you constrain them.
  4. Exception rate — Some exceptions are fine if they can be routed with context. Constant unstructured exceptions mean the process is not ready.
  5. System readiness — Do the source and target systems have APIs, exports, or connectors you can use? Automation without a place to write results is just another inbox.

Processes that score well on volume, rules, and system readiness — and that have exceptions you can define — are your first wave. Processes that fail on documentation or system access stay on the backlog until those gaps close.

Strong first candidates for AI workflow automation

These map directly to common automation use cases:

  • Accounts payable and purchase documents — Extract invoices, POs, and forms into your ERP so staff stop re-typing line items and vendor details. Classification plus field extraction handles the bulk; mismatches go to a reviewer.
  • Order routing and inventory sync — Move new orders into fulfillment systems and keep inventory counts aligned across channels so people are not copying rows between spreadsheets and order tools.
  • Routine reports — Generate the same weekly or monthly packs from systems of record on a schedule, with alerts when a source feed is late or incomplete.
  • Record validation — Check records against rules, flag mismatches, and send a queue of exceptions to the right owner instead of scanning every row by hand.

Each of those has structured inputs, a clear destination system, and a natural place for human review. That is why they tend to be safer first projects than open-ended “automate the whole back office” ambitions. If your team also needs private Q&A over policies while they design these flows, RAG explained covers how retrieval over your own documents works.

Which processes should stay manual

Automation is not the goal for every step. Keep these with people:

  • Judgment-heavy work — Negotiations, novel customer exceptions, and decisions that depend on unwritten context. The automation can gather facts; a person should decide.
  • Rare one-offs — A process that runs a few times a year rarely earns the cost of design, testing, and maintenance.
  • Poorly documented processes — If nobody can write the happy path and the exception list, fix the process first. Automating fog creates faster fog.
  • High-stakes exceptions that need clear ownership — Compliance holds, large credit decisions, safety-critical overrides, and anything where a wrong write to a system of record has serious consequences. Route the case to a named person with the full context; do not let the workflow close it alone.

A healthy design assumes exceptions will happen. Good automations route those cases to a person with the original document, the extracted fields, and why the rule failed — then continue after the person acts.

How to start without replacing your systems

A practical sequence looks like this:

  1. Map — Walk the current process with the people who run it. Capture inputs, systems, rules, and where work stalls. Produce a short automation plan that lists what stays manual.
  2. Connect — Wire document intake, extraction/classification where needed, and system-to-system writes or scheduled jobs. Prefer connectors to the tools you already use.
  3. Exceptions — Define what counts as a mismatch, who owns the queue, and what context travels with each alert.
  4. Dashboards — Show volume processed, exception rates, and aging items so owners can see whether the workflow is healthy.

Delivery should include handoff documentation and training so your team can operate the workflow. GrtLabs can stay involved after go-live when you want ongoing support. Start with one high-scoring process, prove the exception path, then expand.

Frequently asked questions

Which processes should stay manual?

Keep manual any work that depends on judgment, runs rarely, is poorly documented, or involves high-stakes exceptions that need a clear human owner. Automations should gather data and apply rules; people should decide novel cases, compliance holds, and anything where a wrong update to a system of record carries serious consequences.

Do we need to replace our current systems to use AI workflow automation?

No. Effective AI workflow automation connects the tools you already use — ERP, order systems, file stores, and related apps — through integrations and scheduled workflows. The goal is to remove re-keying and handoffs, not to rip out systems that already hold your records.

What happens when an automated workflow hits an exception?

Exceptions should route to a person with context: the source document or record, the fields the automation extracted, and why the rule failed. Alerts and dashboards keep those cases visible until someone resolves them, then the workflow can continue.

Map your first automation with GrtLabs

GrtLabs designs and builds AI and workflow automations that remove repetitive work from documents, orders, inventory, and back-office processes — with process mapping, document AI, integrations, exception handling, and dashboards. If you want help choosing which process to automate first, talk to our team.

  • 1
  • 2